Database App Builder
Build a database app in minutes for free with AI. Write in plain English or tap buttons to create your app.
How to Use the Database App Builder
Step 1: Share your database app's features and requirements.
Step 2: Replit generates your app instantly.
Step 3: Customize features and user experience.
Step 4: Launch your new database app.
Database App Builder Example
Built with Replit.
Build your vision in minutes for free without writing a single line of code.
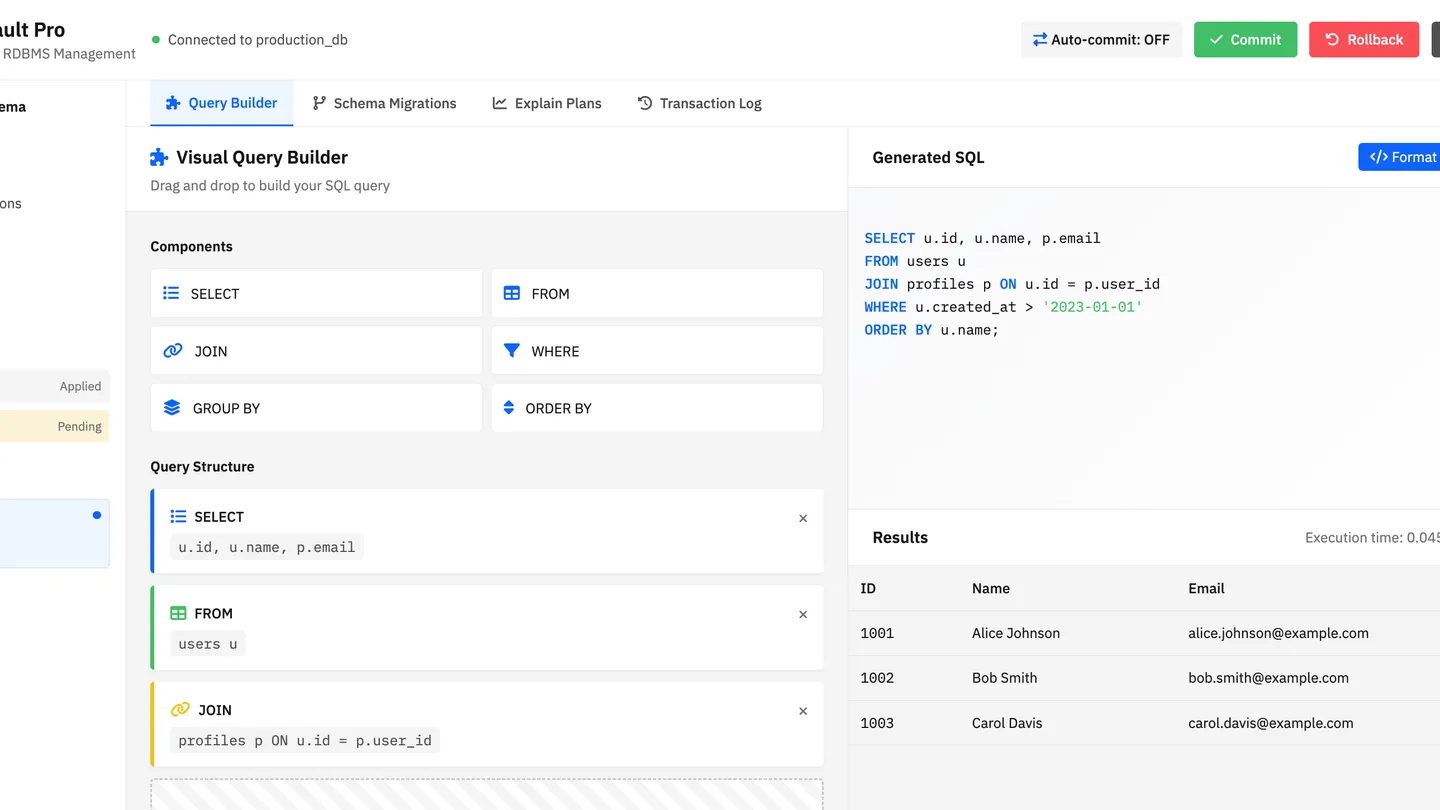
Example
Database App Builder
Prompting the Database App Builder
Rdbms Database App Builder Prompt
Build an RDBMS app that supports fully ACID-compliant transactions (commit, rollback, savepoints), includes versioned schema migrations with up/down scripts and dependency checks, provides an index advisor that analyzes query plans to recommend optimal and detect unused indexes, and offers a drag-and-drop SQL visual builder with live explain plans.
Use promptTsdb Database App Builder Prompt
Build a TSDB app optimized for append-only, batched, compressed high-ingest writes that handle massive telemetry/metrics streams without backpressure; automate tiered retention with continuous downsampling (e.g., 1s→1m→1h); support native time-window aggregations (tumbling, hopping, session); and include built-in real-time anomaly and seasonality detection.
Use promptIn-Memory Database App Builder Prompt
Build an in-memory database that serves data from RAM with sub-millisecond reads/writes for caching, leaderboards, and real-time personalization; supports durable persistence via snapshots and append-only logs with fast recovery; provides pub/sub and stream primitives with consumer groups for real-time event processing; and implements smart eviction (LRU, LFU, TTL) with autoscaling hooks to keep memory usage predictable under bursty workloads.
Use promptVector Database App Builder Prompt
Build a vector database app with ANN search using HNSW, IVF, and PQ indexes; hybrid queries combining keyword, BM25, and vector similarity; embedding generation and update pipelines with popular models; and structured metadata filters, faceting, and re-ranking for precise, scalable semantic retrieval.
Use promptTop Database App Features by Type
ACID Transactions
Support fully compliant ACID transactions with commit, rollback, and savepoints. This ensures data integrity and consistency for OLTP workloads where correctness is critical.
Schema Migrations
Provide versioned schema migration tooling with up/down scripts and dependency checks. This makes evolving complex relational schemas safe and predictable across environments.
Index Advisor
Analyze query plans to recommend optimal indexes and detect unused ones. This improves performance and lowers storage costs without guesswork.
SQL Visual Builder
Offer a drag‑and‑drop SQL query builder with live explain plans. This speeds up development and helps users learn and optimize queries visually.
High-Ingest Writes
Optimize for append-only, batched time-series writes with compression. This handles massive telemetry and metrics streams without backpressure.
Retention & Downsampling
Automate tiered retention policies with continuous downsampling (e.g., 1s to 1m to 1h). This controls storage growth while preserving trend visibility.
Windowed Aggregations
Provide native time-window aggregations like tumbling, hopping, and session windows. This enables fast analytic queries that align with time semantics.
Anomaly Detection
Include built-in anomaly and seasonality detectors for streams. This surfaces operational issues and unusual patterns in real time.
Ultra-Low Latency
Serve data from RAM with sub-millisecond reads and writes. This is ideal for caching, leaderboards, and real-time personalization.
Durable Persistence
Support snapshots and append-only logs with fast recovery. This provides safety against crashes without sacrificing speed.
Pub/Sub Streams
Offer lightweight pub/sub and stream primitives with consumer groups. This enables real-time event processing directly in the datastore.
Smart Eviction
Implement configurable eviction policies like LRU, LFU, and TTL with autoscaling hooks. This keeps memory usage predictable under bursty workloads.
ANN Search
Provide approximate nearest neighbor search with multiple index types (HNSW, IVF, PQ). This delivers fast semantic retrieval at scale.
Hybrid Search
Combine keyword, BM25, and vector similarity in one query. This improves relevance by blending lexical and semantic signals.
Embedding Pipelines
Integrate embedding generation and update pipelines with popular models. This simplifies ingestion and keeps vectors fresh as data changes.
Metadata Filters
Support structured metadata filtering, faceting, and re-ranking. This enables precise, context-aware retrieval for production applications.
The Database App of Your Dreams
Get started freeFAQ about the Database App Builder
How do I start building a database app entirely in my browser with AI?
Open Replit and choose Create with Replit Agent to generate your app from a prompt, or Build from Scratch for full control with Assistant helping along the way. You can also Remix a community project, Import from GitHub to continue an existing codebase, or use Figma import to turn designs into a working UI. Code runs instantly with a real-time preview, and you can iterate using the Agent and Assistant chat. When ready, deploy in minutes from the same workspace.
Which database options are available and when should I use each?
Replit offers a built-in key-value store via Replit Database for simple settings, counters, and session-like data. For relational needs, use a managed database like PostgreSQL to define tables, enforce a schema, and create indexes for performance. Start with the key-value store for lightweight prototypes and move to PostgreSQL as your data model grows. The Agent can provision and connect these services for you during app generation.
How do I model data, run migrations, and seed initial records?
Begin by outlining your schema (an ERD on paper is fine) and ask Replit Agent to scaffold models and migration scripts. You can use raw SQL or your preferred ORM (e.g., Prisma, SQLAlchemy, or drizzle-orm), and the Assistant will help refine or explain the code. Have the Agent generate seeding scripts to create initial records or import sample data. Iterate in the editor, run migrations, and re-seed as needed directly from your browser.
How do I connect my app to the database securely?
Store your database connection string in the Secrets manager and reference it via environment variables in code. Use SSL/TLS for connection encryption on your deployed app and database where supported. Rotate keys by updating secrets and redeploying, and follow least privilege by creating scoped DB users. The Agent and Assistant can help add secure config boilerplate without exposing credentials in your repository.
Can AI generate my CRUD API and queries, and help debug database errors?
Yes—ask Replit Agent to scaffold a CRUD REST API (or GraphQL if you prefer) and it will generate routes, handlers, and SQL or a query builder pattern. Assistant provides autocomplete as you extend endpoints and write queries. When something breaks, share the error message or stack trace and Assistant will propose fixes with a previewable code diff. You stay in control by reviewing and applying changes inline.
How do checkpoints and rollbacks affect my database data?
Every significant change creates a checkpoint—a snapshot of your project, including code, environment, and connected database state. If something goes wrong, use rollback to restore the exact checkpoint, effectively an undo that preserves data integrity. This works alongside version control, giving you quick restore points beyond regular commits. Experiment freely knowing you can always restore and continue safely.
How do I integrate auth, payments, and messaging with my database app?
Mention services in your prompt and Replit Agent wires them up: Replit Auth, Google OAuth, or Firebase Auth for login; Stripe or PayPal for payments; SendGrid or Twilio for emails and SMS with webhooks. The Agent adds SDK initialization, example routes, and database hooks to store users, subscriptions, and message logs. Provide API keys via the Secrets manager and test flows in the real-time preview. Deploy when ready and scale features with Assistant’s help.
What are the limits of drag-and-drop when building database apps here?
Replit includes a visual editor for UI tweaks, but drag-and-drop is limited to refining the interface rather than building full apps. Backend logic, state management, and data binding are code-driven, with AI code generation helping you move fast. Think of the visual editor as a way to adjust text, images, and styles while the Agent/Assistant handle deeper changes. For complex workflows and data models, you’ll work in code with AI assistance instead of no-code drag-and-drop.
What are you waiting for?
Build an app without knowing how to code. Tell Replit what you have in mind, then make it your own.